

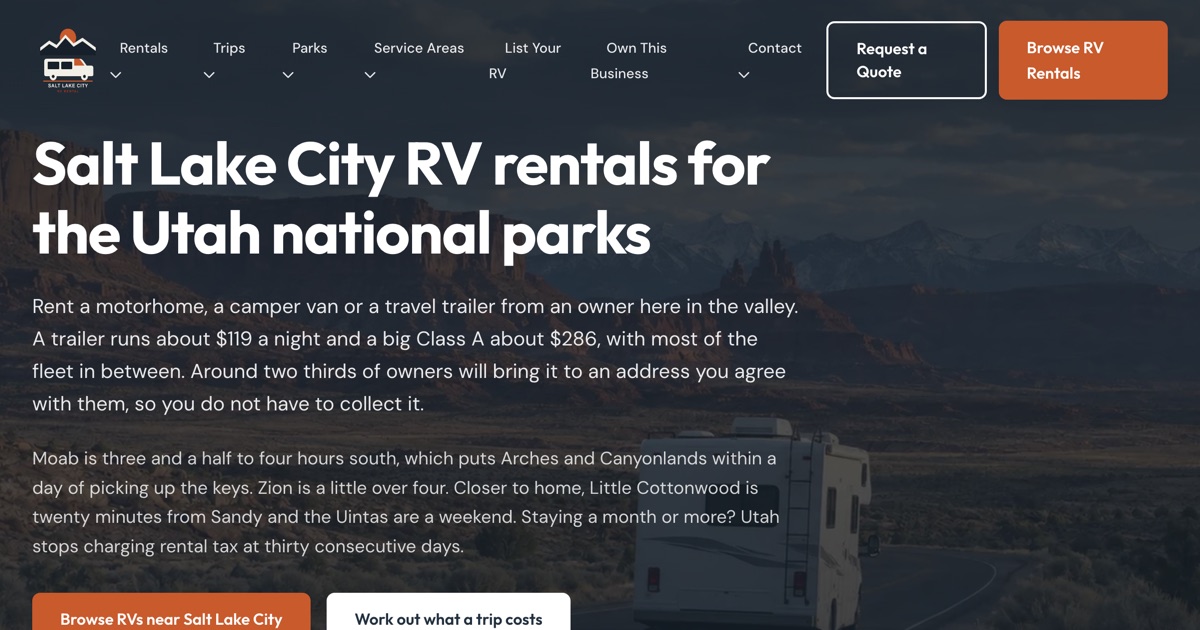
On September 20, 2026, an audit of saltlakecityrvrental.com found that 11 of the 25 sentences on its homepage, 44%, carried a vehicle size token like “ft”, “width” or “tunnel”. The cause was a voice rule I had written two days earlier and backed with a test, and the site followed it exactly.
Salt Lake City RV Rental is my own site. Claude Code and I built it in 53 commits between September 18 and 21, 2026, and every one of them is co-authored by Claude. This post covers what the rule said, how the 44% was measured, how I reproduced it from the git history, and the two times the fix failed the same way.
What did the voice rule actually say?
The first commit shipped a voice bible, docs/voice-bible.md, with this house tone: “Write the constraint, then the consequence, then what it costs to get wrong.” Its example of a good opening was “your mirrors are part of the measurement.”
That is my house method, consequence writing. It is a good rule for a page about one park’s road limits. The site also had commercial pages: the homepage, the listings, the class and city pages. The rule did not say which pages it was for.
A second document, the topical map, said the opposite in its last line: “A site made only of constraints answers no query that starts with ‘I want to’.” The voice bible won because it had src/data/constraints.test.ts behind it, a test suite the build runs. The topical map was prose nobody’s build can fail. The repo’s own instructions to Claude say “Extend the test rather than working around it.”
A second check pushed the same way. On September 19 I added scripts/check-voice.ts, an AI judge that fails any passage that would survive swapping in another city. Its printed advice for every failure is “Anchor each of these to a road, a limit or a measured figure that exists only here.” A size limit is the cheapest thing that passes that check. That last point is my reading, not the audit’s.
How was the 44% measured, and can you reproduce it?
The audit, docs/content-audit-2026-09-20.md, counted the share of visible sentences carrying any of 13 size tokens, per page template. The guard that shipped with the fix reads sentences out of each page’s source file with one regular expression. I ran that same function against the homepage file at every commit that touched it.
// the guard's own sentence reader, from constraints.test.ts
source.replace(/\/\*[\s\S]*?\*\//g, "").match(/[A-Z][^<>{}"`]{40,400}?[.?]/g)

// the audit's 13 tokens
/\b(ft|feet|inch|wide|width|length|tunnel|oversize|clearance|GVWR|lbs|limit|dimension)\b/i| Commit (date) | Homepage sentences | Audit tokens | Guard tokens |
|---|---|---|---|
| 5136a46, first commit (Sep 18) | 26 | 11 (42%) | 9 (35%) |
| 6334987, day before the audit (Sep 19) | 25 | 11 (44%) | 7 (28%) |
| 1b70a12, the rewrite (Sep 20) | 23 | 2 (9%) | 4 (17%) |
| Today’s code | 29 | 1 (3%) | 2 (7%) |
The 44% reproduces exactly: 11 of 25. So does the audit’s second figure, 28% under the guard’s narrower token list, which drops “limit”. The 17% after the rewrite is the guard’s number, and it reproduces too.
One line in the audit does not reproduce. It says both measures fell to 17%. Under the audit’s own tokens I get 2 of 23, or 9%. The gap is exactly two sentences. In the rewrite, “Every limit here came off the park’s own page” became “Every access rule here came off the park’s own page.” A second sentence changed “these limits” to “these rules.” The meaning did not change. The count did.
The method is crude, and the test file says so. It reads source code, not rendered HTML, and it flags “Mirror Lake Highway” as a size claim. It is good enough to catch drift. It is not a measure of quality.
What does Google’s guidance say about a page like that?
Google’s helpful content guide lists warning signs of search engine-first content. One asks: “Does your content leave readers feeling like they need to search again to get better information from other sources?”
Here is the meta description the homepage carried the day before the rewrite: “Zion scrapped the tunnel permit on 7 June 2026 and now turns oversize RVs around. Only 80 of 610 Salt Lake City listings publish the width that stops you.” The audit’s comment was that someone searching “rv rental salt lake city” got a tunnel warning 300 miles away instead of a price.
Google’s generative AI guidance says it is “critical to manually factcheck and review all AI-generated content,” and that the review “also applies to metadata.” This description would have passed a fact check. Every figure in it traces to a source file. A fact check asks whether it is true. The searcher asks whether it is what they came for.
The finding was true. It answered a question the searcher had not asked yet, so they still needed a price and a vehicle. That is the “search again” signal, produced by a rule meant to make pages more useful.
What it cost in search, I can’t tell you. I have no Search Console or analytics data for this site in the files I worked from, so any traffic number here would be invented.
Did the fix work?
The size share fell. The disease moved. The fix, commit 1b70a12, rewrote the rule to “Open on what the reader came for. Then the fact that changes what they do. Then what it costs to get wrong.” It added a test capping size-token sentences at 25% of any commercial page.
The rewritten homepage hero led with the market instead of the parks. The commit that fixed it, 61 minutes later, quotes it: “610 motorhomes, camper vans and trailers listed within 50 miles of downtown, measured on 2026-09-18.” Then a median price, a price range and a delivery count. Its verdict: “Every figure in that is true, sourced and dated, and none of it is written to a person who wants an RV for a week in Moab.”
The size guard passed it, because its tokens are about size. The commit records that I caught it, not a test, and that seven pages had the same opening. The site’s answer was a third guard, which bans words like “measured on” and “median published” from the first section of most pages.
Then it happened a third time. The voice bible also said “Every figure carries the date it was measured.” The next morning’s commit counted that date printed 86 times across the site. I checked the data files and found 47 literal copies of “measured on 18 September 2026”, which matches the commit. The rule was rewritten: the date stays on the data record and leaves the copy.
Three rules, three overshoots, each one the house method followed to the letter. Name the constraint. Show your number. Date your number. Each is right in the right place. Applied everywhere, each described the dataset to someone who wanted to rent a camper van.
Why does a rule enforced by a test do this?
Economists have a name for it. Charles Goodhart wrote in 1975 that “any observed statistical regularity will tend to collapse once pressure is placed upon it for control purposes.” The common version, from Marilyn Strathern in 1997, is shorter: “When a measure becomes a target, it ceases to be a good measure.”
An AI writer is the purest version of that pressure. It reads the rule, sees the test, and writes to pass it. The “limit” to “rule” swap is what that looks like at the level of one word.
The cap invites the same thing. The contact page went from 8 of 27 size sentences to 7 of 28 in one commit, which is 25.0%, exactly the cap. The test allows a margin of 0.001. That commit also merged two duplicate cards, which is a real reason. I can’t tell from the diff whether the number was aimed at. A page landing exactly on a threshold is the place to look.
Google draws the same line in its own list of warning signs: “Are you writing to a particular word count because you’ve heard or read that Google has a preferred word count? (No, we don’t.)” A share cap is a word count by another name. It is useful as an alarm. Written to, it produces the page Google is warning about.
So should you stop enforcing voice rules with tests?
No. That is the wrong lesson, and the repo has already tried it. A comment in constraints.test.ts records that an earlier guard banned a figure outright, “which would have forced every page to be vague, which is worse than the failure it caught.” The listing page stays pinned at 34% size sentences on purpose. Its remaining size content is a per-vehicle check against four road limits. The file says: “deleting it to satisfy this cap would make the page worse.”
Untested rules lose, as the topical map did. Tested rules win too hard. What held up here was a narrower test: one position on the page, like the hero or the last heading before the button, with named exemptions.
The cleanest example is the closing-CTA guard. It fails any button or final heading that asks the reader to measure something. On its first run it caught nine, including the affiliate button, which read “Browse listings by length.” That is a rule about where a fact goes, not how often it appears, and it is much harder to game.
Do the guards cover the whole site now?
No. I found this by running the measurement again for this post. A guard only holds where it reads. The size cap and the hero guard read page files. The date sweep covered the data files and the page templates.
The rental policies page draws its prose from a file in src/lib, and none of them read it. Today that file still prints “measured on 18 September 2026” three times, after the voice bible was changed to say “The date does not go in the copy.” Nothing fails, because nothing is looking.
What should you do if your content rules run as tests?
- Scope every rule to the pages it is for. Write the list of page types into the rule itself, and the list of exemptions with a reason for each. “Write the constraint first” failed because it did not say where.
- Prefer position rules to share rules. “No size limit in the hero” and “no measuring instruction under the button” held. “Under 25% of sentences” invited a page to land on 25.0%.
- Measure with two token lists. Keep one the writer never sees. If the visible metric falls and the hidden one falls further, read the diff for synonym swaps like “limit” to “rule”.
- Read the first screen and the meta description as a searcher would. Ask Google’s question: would they need to search again? No test here caught the market-statistics hero. A person did.
- When you retire a rule, grep for its output everywhere. Search the whole source tree for the phrase it produced, not only the folders your tests read.
- Record each overshoot where the next writer will read it. This repo writes each failure into the test’s comment, which is how I rebuilt this story from git.
One honest note. This post is built from consequence units, the structure that overshot on the RV site. It suits an article that argues one point. It was a bad rule for a homepage whose job is to sell. The fault was applying it to every page without saying which ones.
The same failure, a check that passes work it should catch, shows up in a programmatic SEO quality gate for generated pages and in automated level testing on a game built with Claude Code.
Sources
- Google Search Central, Creating helpful, reliable, people-first content (page updated 2026-10-05).
- Google Search Central, Guidance on using generative AI content on your website (page updated 2026-10-01).
- Wikipedia, Goodhart’s law, for Goodhart’s 1975 wording and Strathern’s 1997 phrasing (page last edited 2026-10-09).
- The saltlakecityrvrental.com repository:
docs/content-audit-2026-09-20.md,docs/voice-bible.md,src/data/constraints.test.ts,scripts/check-voice.tsand commits 5136a46, c4f380c, 1b70a12, d520a9c, 07183b7 and d6ec2d5, read October 10, 2026.


